The score belongs to a run
Parminder Kumar Sharma’s analysis of Sonnet 5.5’s Terminal-Bench result asks how effort settings and task cost qualify Anthropic’s comparison with Opus 5.5. That is the editorial cue I would carry into this different comparison: before treating Anthropic’s and Vals AI’s Sonnet 5.5 figures as a contest, identify the systems that produced them.
Advertisement
The tempting reading of a benchmark table is that it ranks models as if they were isolated objects. The higher number wins. But a coding agent is a chain: model, API, tool interface, instructions, retry rules, time and output limits, and a verifier that decides whether the result counts. Change one of those, and the score may change even if the model weights do not.
That distinction matters in Claude Sonnet 5.5’s Terminal-Bench result. Anthropic reports 70.6%, compared with 10.3% for Sonnet 5 and 66.4% for Opus 5.5. Its linked system card says the Sonnet 5.5 run used Claude Code in bare mode at max effort, with 66 tasks averaged across five trials each and no internet access. Server-side fallback handled safeguard flags on 1.2% of requests, affecting 1.5% of trials; one attempt stopped instead of replying. Anthropic reports a standard error of ±2.5 points. Those details describe its own run, not an independent reproduction.
Vals AI, which evaluates models through its own published benchmark suite, reports 53.03% for Sonnet 5.5 on Terminal-Bench 4.0. Its page gives more detail: three full benchmark runs, 66 tasks per run, the Terminus 2 reference agent, maximum compute effort, temperature 1, and a 128,000-token output limit. Vals also reports a standard error of 1.51 points across the runs.
Those two figures are a real difference between reported outcomes, but they are not a controlled comparison of model weights. Anthropic’s system card gives considerably more detail than the launch table, while Vals does not claim to reproduce its setup. We should not turn the 17.57-point gap into a verdict about either company. The useful question is what each run actually tested.
One benchmark name, more than one setup
Terminal-Bench is designed to test long, multi-step work in a sandboxed command line. Its tasks can ask an agent to produce a working service, train a kernel, create a CAD model, or prepare a forensic report. Each task is graded against its final artifact. A model that can reason through the task still has to interact reliably with the agent harness, command line, environment, and verifier.
Vals says it uses Terminus 2, Harbor’s reference agent, with the upstream configuration unless it notes an exception. The agent presents a task and a terminal session; the model sends keystrokes and reads the screen. Vals says the harness has no structured-output mode. If a response contains invalid or missing JSON, it retries with a warning. The task must pass its full verifier to receive credit, and the run has an eight-hour agent limit.
Vals also describes a fallback rule. When Sonnet 5.5 refused, the service could route the attempt to Sonnet 5. Seven of the 198 attempts used that fallback. Vals reports 53.03% with those assisted attempts included and 50.51% if they are counted as failures.
These details do not explain the difference from Anthropic’s 70.6%. Both evaluators disclose meaningful methods, but they used different agents: Claude Code in bare mode for Anthropic and Terminus 2 for Vals. Their published material does not provide a controlled rerun through one harness with matched prompts, settings, task snapshots and task-level outcomes. “Sonnet 5.5 on Terminal-Bench 4.0” is not a complete description of an experiment.
This is the standard I would use for any striking agent score: identify the model and version, name the harness, preserve the task snapshot, report effort and resource limits, count fallbacks, and show how many runs produced the average. Without those details, the score may still be informative about one setup, but it cannot settle a model-versus-model comparison.
The benchmark changes under maintenance
Terminal-Bench 4.0 was itself a substantial revision. The maintainers calibrated time, CPU, and memory; removed eight tasks they considered saturated; and fixed 19 tasks by changing instructions, environments, or verifiers. Every 4.0 task has a flat eight-hour agent timeout. The maintainers say the changes to the task set and resources require rerunning trials, and that 4.0 scores should not be compared numerically with version 3.0.
The project’s notes also describe a problem with the previous Sonnet 5 run. It sometimes timed out or exceeded output limits, and the maintainers observed wide variation in execution time. The leaderboard run used 21.6 billion tokens for Sonnet 5, compared with 6.5 billion for Opus 5. The maintainers note that they had not enabled a 128,000-token maximum output setting for Sonnet 5, which might have helped it stay within its output limit.
That is useful context for the predecessor’s public-board run, but it is not an explanation for the 70.6% Sonnet 5.5 result. The benchmark maintainers do not say that a longer output allowance caused the new model’s score. The public predecessor run and Anthropic’s Sonnet 5.5 run are separate measurements; a plausible mechanism is not a verified cause.
There is a separate question about whether the benchmark’s tasks and grading are dependable. Epoch AI’s review of Terminal-Bench 4.0.0 identified publicly reported scoring defects in 30 of its 66 tasks and labeled that version “Flawed” under its review criteria. Its examples include grading that can be bypassed, answers exposed in the environment, and requirements strict enough to mark plausible solutions wrong. Epoch said ten fixes were pending at the time of its review.
The benchmark maintainers also describe an active process for public issue reports, task fixes, and future revisions. That is a strength of an open benchmark: people can inspect the tasks and verifiers and report errors. It does not make the current version error-free. Epoch’s review is a warning about the benchmark version, not evidence that Anthropic or Vals benefited from a particular defect. No available source connects either Sonnet 5.5 score to reward hacking, leaked answers, or false negatives on a specific task.
The bug disclosure is about other tests
Anthropic’s launch page includes a separate disclosure about a pre-release bug that could degrade structured-output responses. It says the affected evaluations were GDPval-AA and AA-Briefcase, run by Artificial Analysis on a pre-release deployment; Anthropic expected any impact to be small and to understate Sonnet 5.5’s performance, and says the bug has since been fixed.
That disclosure is relevant because it shows how a model’s API behavior can matter to a measured result. But it should not be folded into the Terminal-Bench story. Anthropic does not say the bug affected Terminal-Bench, and the systems involved are not interchangeable. The careful reading is narrower: a release may disclose a limitation in one set of evaluations, while leaving another benchmark’s configuration to be assessed on its own evidence.
What the numbers can tell a team
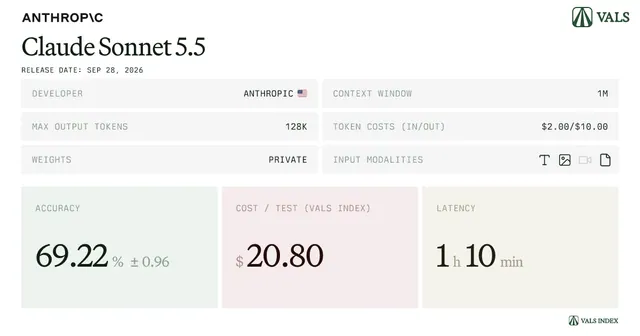
There is evidence here for taking Sonnet 5.5 seriously. Vals’ model page reports strong results across its wider collection of evaluations, including a 69.22% Vals Index score that placed it second among 66 models in that snapshot. On Terminal-Bench 4.0, Vals’ 53.03% also places it among the leading entries in its run. These results do not make the model weak; they make the single headline less sufficient as a model-selection guide.
For an engineering team, a public score is a starting point for choosing what to test. If the intended use is a coding agent, compare models through the harness, tools, permission boundaries, repositories, and task mix the team will actually deploy. Record completion quality and failure types, not only whether a final verifier passed. A public benchmark can help identify a candidate; it cannot predict how a different harness or workflow will behave without further evidence.
When published scores differ, a useful next step is a task-level comparison, not another debate about whose headline is more believable. Ask which tasks each run passed, how often results varied between trials, where a retry changed the outcome, and whether a fallback model completed any attempt. For an internal evaluation, hold the task set, tool versions, permissions, time budget, and success criteria steady; run more than once; then report both completion rate and failure categories. This makes the decision useful even if the public benchmark itself is imperfect. It also gives the team a way to retest after changing its harness, instead of carrying a vendor’s percentage into a different environment.
The rate card and the task bill are also separate questions. Anthropic says Sonnet 5.5 uses the same token prices as Sonnet 5 and costs up to 30% less per task in its own tests. Vals reports its own cost per task for its setup. Those figures should not be used to explain this benchmark gap, but they underline the same practical point: a result is attached to a workload and a measurement procedure. A lower token price or a higher pass rate alone does not establish a lower cost for a team’s accepted work.
A better release-day comparison
A release score can still be useful, but comparison requires a reporting standard. Anthropic’s system card supplies substantial method detail beyond its launch table. A matched comparison would require the evaluators to use or disclose the same model identifier, harness and prompt, effort, sampling settings, output and time limits, retries, fallback policy, and task version, then report run-level and task-level outcomes. Those task details matter particularly while benchmark maintainers and reviewers are documenting defects in the test set.
Sharma’s Sonnet analysis starts within Anthropic’s own table, asking how effort and task cost change the comparison with Opus. The same discipline applies across Anthropic’s and Vals’ Sonnet runs: both reported results can be useful, but their difference remains unexplained until the conditions are matched.
Until then, read 70.6% as Anthropic’s result under its reported evaluation, and 53.03% as Vals AI’s result under a disclosed Terminus 2 setup. Both are evidence. Neither number, by itself, tells us why the other is different. The rule I would use when choosing a model for a coding agent is simple: ask what system produced each score before asking which model won.